Cyfuture Logo
About Banner
Cloud & Infrastructure

GPU Clusters

High-Performance GPU Clusters with GPU as a Service

Overview

High-Performance GPU Clusters for AI & Deep Learning

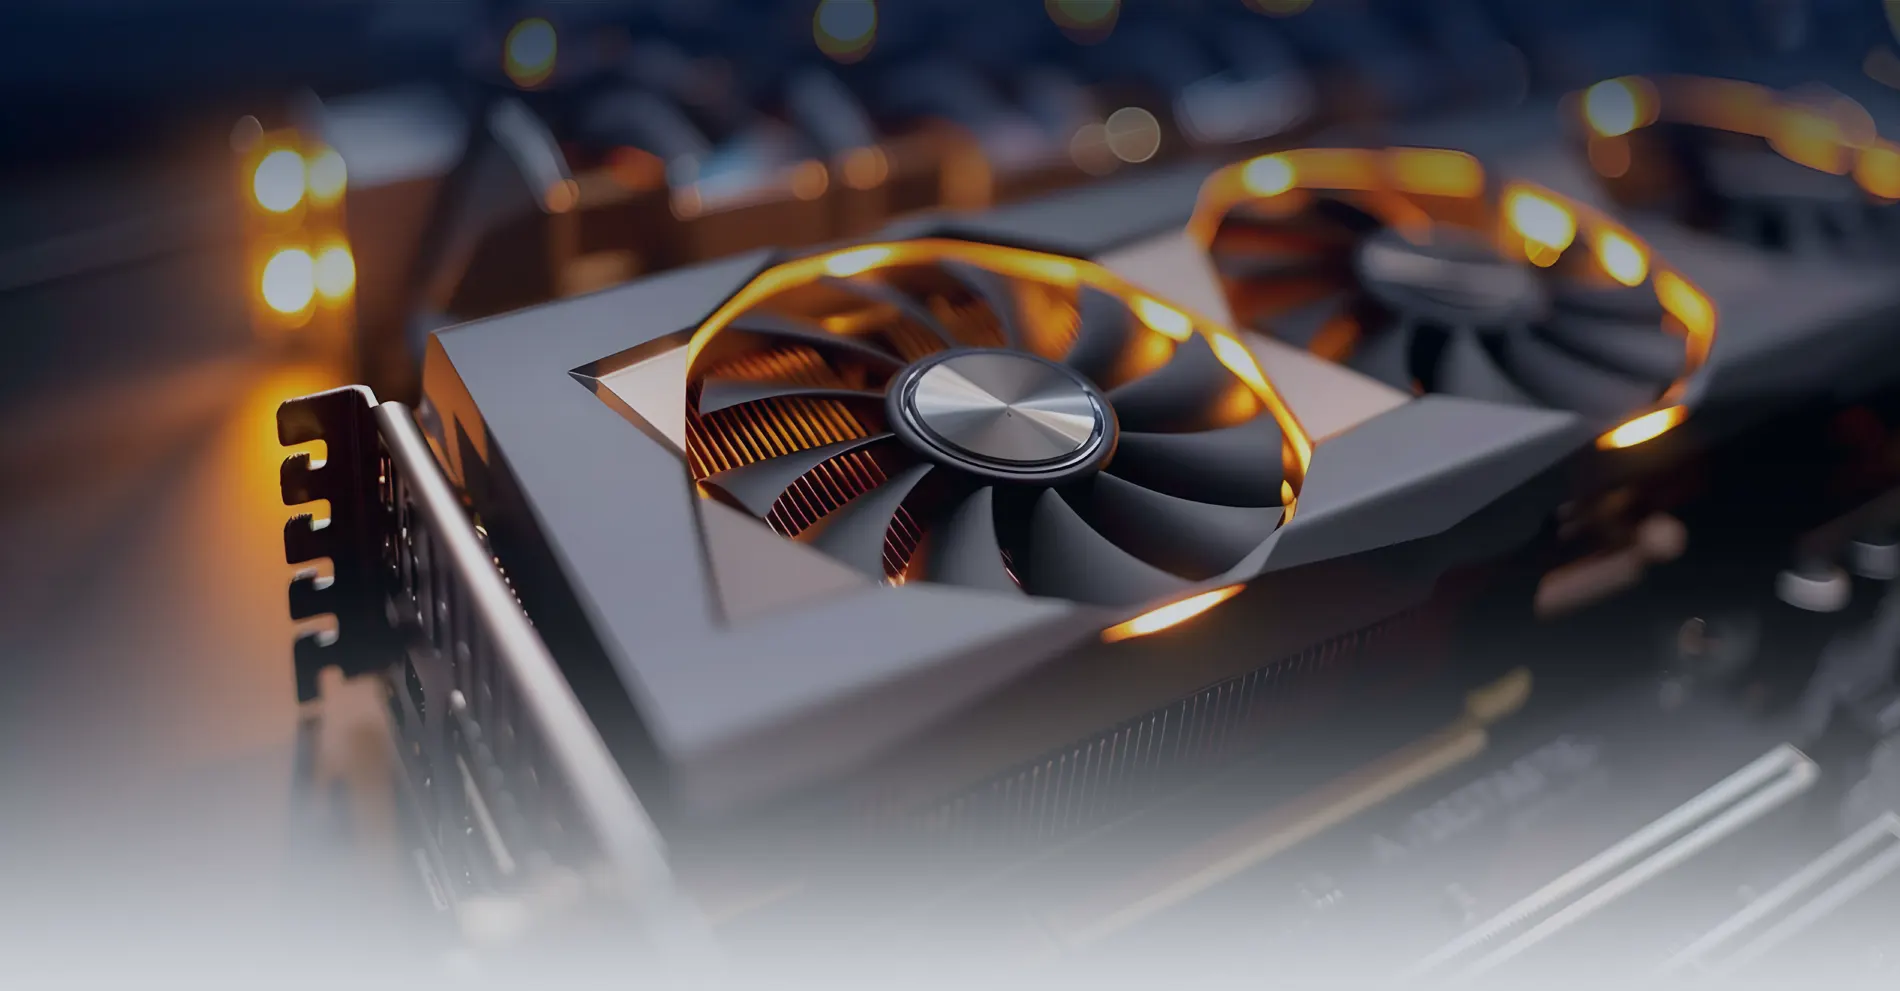
Cyfuture’s GPU clusters deliver unparalleled performance tailored for AI, machine learning, and deep learning workloads through our GPU as a service offering. Powered by the latest NVIDIA GPU technology—including A100, H100, and V100 GPUs—our clusters drastically reduce training times for complex models and enable real-time analytics. Whether you’re running large-scale machine learning experiments or deploying deep learning algorithms, Cyfuture’s NVIDIA GPU cluster infrastructure ensures seamless scalability, high throughput, and efficiency, making it the ideal choice for enterprises and research institutions handling computationally intensive tasks.

Built for speed, reliability, and flexibility, our GPU clusters leverage advanced cooling systems, low-latency networking, and enterprise-grade security to optimize performance across diverse AI applications. From neural network training to high-performance data processing, Cyfuture’s GPU as a service platform provides a robust, scalable foundation that accelerates innovation while maintaining cost-effectiveness. With easy integration and on-demand access, businesses can harness cutting-edge GPU power without the overhead of hardware management, staying ahead in the rapidly evolving AI landscape.

Let's Talk!

Your information is 100% secure with us.

What is a GPU Cluster?

GPU clusters combine multiple GPUs to deliver fast, scalable computing for AI, deep learning, simulations, and data analytics. With GPU as a Service, businesses can access this power on-demand without costly hardware investments.

GPU Clusters for AI & Deep Learning

GPU clusters accelerate AI and deep learning by distributing workloads across multiple GPUs, enabling faster training, scalable performance, and cost-effective GPU-as-a-Service access.

Technical Specifications: GPU Cluster

Hardware Configuration

Managed Cloud Hosting Solution for Finance

GPU Nodes

  • GPU Type: NVIDIA A100 / H100 / RTX 6000 Ada (Latest Tensor Core GPUs)
  • GPUs per Node: 4x / 8x (Configurable based on workload)
  • GPU Memory: 40GB/80GB HBM2e (A100) | 80GB HBM3 (H100)
  • Interconnect: NVLink (600GB/s bandwidth) & PCIe Gen 5.0
Managed Cloud Hosting Solution for Finance

CPU

  • Processor: AMD EPYC 9004 / Intel Xeon Scalable (Latest Gen)
  • Cores per Node: 64/128 Cores
  • Clock Speed: Up to 3.7 GHz (Boost)
Managed Cloud Hosting Solution for Education

Memory

  • RAM per Node: 512GB – 2TB DDR5 ECC
  • Bandwidth: Up to 4800 MT/s
Managed Cloud Hosting Solution for Manufacturing

Storage

  • Primary Storage: NVMe SSD (7GB/s read/write)
  • Capacity: 10TB – 100TB per Node (Scalable)
  • Parallel File System: Lustre / GPFS for distributed storage
Managed Cloud Hosting Solution for Media and Entertainment

Networking

  • Inter-node Connectivity: 200Gbps InfiniBand / 400Gbps Ethernet (RDMA support)
  • Latency: <1μs (InfiniBand)

Software Stack

Managed Cloud Hosting Solution for Finance

AI/ML Frameworks

  • TensorFlow, PyTorch, MXNet, ONNX Runtime
  • CUDA 12.x, cuDNN 8.9, NCCL for multi-GPU communication
Managed Cloud Hosting Solution for Finance

Orchestration & Deployment

  • Kubernetes (K8s) with NVIDIA GPU Operator
  • Slurm / Apache YARN for HPC workloads
  • Docker & Singularity for containerized workloads
Managed Cloud Hosting Solution for Education

Monitoring & Management

  • NVIDIA DCGM for GPU health tracking
  • Prometheus + Grafana for real-time metrics
  • Custom dashboards for cluster utilization

Performance & Scalability

Managed Cloud Hosting Solution for Finance

Compute Power

  • FP64 Performance: ~20 TFLOPS per GPU (A100)
  • AI Inference (FP16/INT8): Up to 624 TOPS (H100)
  • Scalability: Horizontal scaling to 1000+ GPU nodes
Managed Cloud Hosting Solution for Finance

Latency & Throughput

  • Inference Latency: <5ms (for lightweight models)
  • Throughput: 100,000+ inferences/sec per GPU

Security & Compliance

  • Data Encryption: AES-256 (At rest & in transit)
  • Compliance: ISO 27001, SOC 2, HIPAA (Configurable)
  • Access Control: RBAC (Role-Based Access Control)

Use Case Optimization

  • AI Inferencing: Optimized for batch + real-time inference
  • HPC Workloads: CFD, Molecular Dynamics, Rendering
  • LLM Serving: Support for 100B+ parameter models

Why Choose Cyfuture’s GPU Clusters?

  • Private Cloud

    Unmatched Computational Power

    Harness the power of NVIDIA GPU clusters with cutting-edge GPUs like A100, H100, and V100, optimized for parallel processing and AI workloads.

  • Public Cloud

    Optimized for AI & Deep Learning

    Our GPU cluster for machine learning and GPU cluster for deep learning ensures rapid data processing, reducing training times from weeks to hours.

  • Hybrid Cloud

    Scalable & Flexible Infrastructure

    Easily scale your GPU clusters based on workload demands, with customizable configurations to fit your project requirements.

  • Multi-Cloud

    High-Speed Networking & Low Latency

    Benefit from ultra-fast NVLink and InfiniBand interconnects, ensuring seamless communication between GPUs for distributed computing.

  • Distributed Cloud

    Cost-Effective & Secure

    Reduce infrastructure costs with our pay-as-you-go model while enjoying enterprise-grade security and compliance.

Key Features of GPU Clusters

High-Performance Computing (HPC) Capabilities

  • Massive Parallel Processing: Thousands of CUDA cores per GPU accelerate complex computations.
  • Multi-GPU Support: NVLink/PCIe interconnects enable seamless multi-GPU communication.
  • Low-Latency Networking: InfiniBand/RDMA reduces data transfer delays between nodes.

Advanced Storage & Data Management

  • High-Speed NVMe Storage: 7GB/s read/write speeds for I/O-intensive tasks.
  • Parallel File Systems: Lustre/GPFS for distributed data access.
  • Data Pipeline Integration: Compatible with Apache Spark, Dask, and Kubeflow.

AI & Machine Learning Optimization

  • Tensor Core Acceleration: Dedicated AI cores (NVIDIA Ampere/Hopper) for faster FP16/INT8 inference.
  • Framework Support: Pre-installed libraries (TensorFlow, PyTorch) with GPU-optimized kernels.
  • Large Model Training: Supports LLMs, diffusion models, and billion-parameter networks.

Security & Compliance

  • End-to-End Encryption: AES-256 for data at rest and in transit.
  • Zero-Trust Architecture: Role-based access control (RBAC) and audit logs.
  • Certifications: ISO 27001, SOC 2, HIPAA, and GDPR-ready configurations.

Scalability & Flexibility

  • Elastic Scaling: Dynamically add/remove GPU nodes based on workload demands.
  • Hybrid Cloud Integration: Burst to public cloud GPUs (AWS/Azure) during peak loads.
  • Multi-Tenancy: Isolated environments for different teams/projects.

Energy Efficiency

  • Power-Efficient GPUs: NVIDIA’s latest architectures (e.g., H100) deliver higher performance per watt.
  • Dynamic Power Capping: Adjust GPU TDP to optimize energy use.

Enterprise-Grade Reliability

  • Redundant Power/Cooling: 2N power backup and liquid cooling options.
  • Automated Failover: Self-healing node recovery for mission-critical workloads.
  • SLA-Backed Uptime: 99.9% availability guarantee.
24/7 Technical Support

Simplified Management

  • Unified Dashboard: Monitor GPU utilization, temperatures, and job queues in real time.
  • Automated Provisioning: Deploy clusters with Terraform/Ansible scripts.
  • API-Driven Operations: REST APIs for integration with CI/CD pipelines.
Why us?

Use Cases for GPU Clusters

1

AI & Machine Learning Model Training

2

Deep Learning & Neural Networks

3

Big Data Analytics & Real-Time Processing

4

Scientific Simulations & Research

5

High-Performance Computing (HPC)

FAQ’s

Frequently Asked Questions (FAQ)

A GPU cluster is a group of interconnected GPUs (Graphics Processing Units) designed to handle parallel processing tasks efficiently. Cyfuture’s NVIDIA GPU clusters accelerate AI, machine learning, and deep learning workloads by providing massive computational power, reducing training times, and enabling real-time inferencing for large-scale models.

Unlike CPUs, NVIDIA GPU clusters excel at parallel processing, making them ideal for deep learning and machine learning tasks. Cyfuture’s clusters deliver:

  • 10-100x faster model training.
  • Scalability for large datasets.
  • Energy efficiency for cost-effective high-performance computing.

Yes! Cyfuture offers tailored GPU cluster solutions based on workload requirements. Whether you need a GPU cluster for deep learning (with high-memory GPUs like NVIDIA A100) or a machine learning cluster optimized for real-time analytics, we provide flexible configurations.

Our NVIDIA GPU clusters feature:

  • High-speed NVLink/InfiniBand interconnects for minimal latency.
  • Redundant storage & networking for 99.9% uptime.
  • Global data center presence to reduce geographical delays.

Cyfuture’s GPU clusters are used across sectors, including:
  • Healthcare (medical imaging, drug discovery).
  • Finance (fraud detection, algorithmic trading).
  • Autonomous Vehicles (computer vision, sensor data processing).
  • E-commerce (personalized recommendations, NLP chatbots).